Train models you actually own.
Training clusters, inference platforms and AI factories sized to your model, your data and your power envelope.
The constraint
Foundation-model and large fine-tuning work burns through cloud credits fast, and reserved cloud capacity usually means long commitments on someone else's terms. Owning the cluster changes the economics for steady workloads, but only if network, storage, power and cooling are designed together. A training cluster runs at the speed of its slowest link.
Workloads
Foundation model pre-training
Train from scratch on a dedicated cluster, with a high-bandwidth GPU fabric and storage that keeps every GPU fed.
Fine-tuning & post-training
Run supervised fine-tuning, preference tuning and distillation on your own data.
Production inference
Serve models at scale, with batching and quantisation tuned to your latency and cost targets.
AI data centres & AI factories
Stand up a full training and inference facility as one build.
Systems
- GLabs AI Factory — cluster- and facility-scale AI infrastructure.
- GLabs GPU Servers — training and inference nodes.
- GLabs Vault — datasets and checkpoints, at the throughput training needs.
- GLabs AI Workstations — developer seats.
Deployed with
GLabs AI Stack, from the first workstation to the full cluster.
Related solutionsFoundation Model Pre-TrainingAI Data Centers & AI Factories
FAQs
How big a cluster do I need to pre-train a model?
It depends on parameter count, training tokens and your timeline. Training compute is roughly six times parameters times tokens, in floating-point operations. We turn that into GPU count, time to train and power draw, then size the cluster to your deadline.
Is owning a GPU cluster cheaper than renting cloud capacity?
It depends on utilisation. Sustained, high utilisation favours ownership; short, bursty work favours the cloud. Many teams run base load on owned hardware and burst to the cloud for peaks.
What interconnect does a training cluster need?
Multi-node training exchanges data between GPUs constantly, so clusters use high-bandwidth, low-latency fabrics such as InfiniBand or RDMA-capable Ethernet, with NVLink inside each node. We design the fabric to your parallelism strategy.
What power and cooling does a modern GPU rack need?
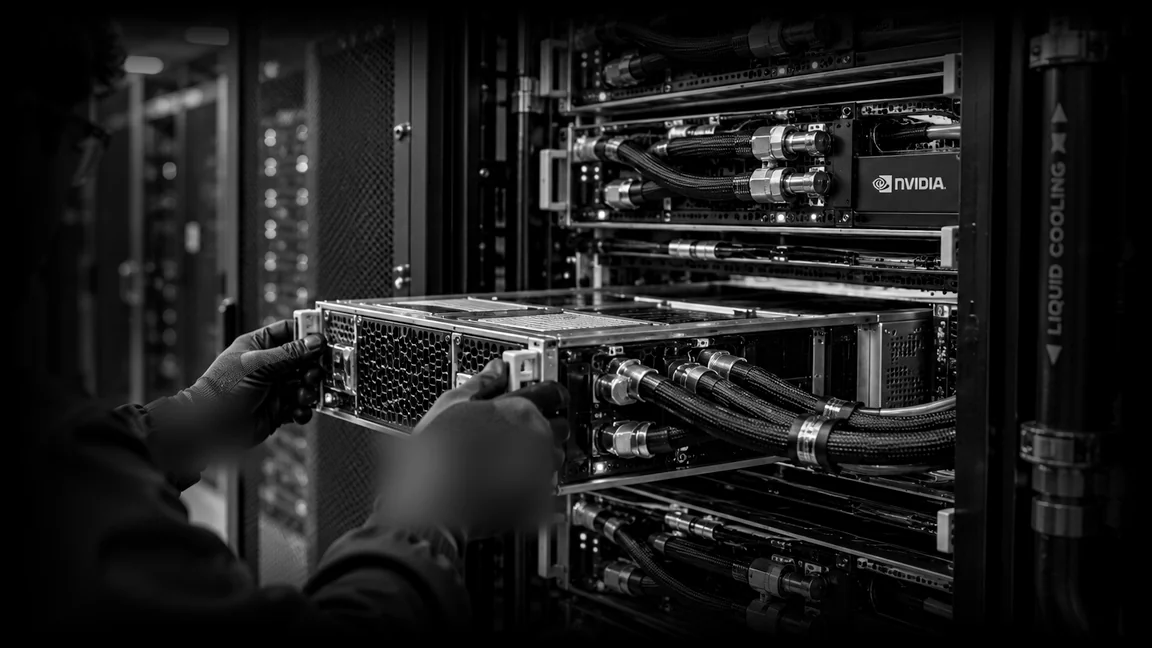
Modern GPU racks draw tens of kilowatts, and the densest liquid-cooled designs go well past 100 kW per rack. We design power and cooling alongside the compute, not after it.
Tell us the model, the data and the deadline. We'll size the cluster.
All product and company names mentioned are trademarks of their respective owners.